A decision model returns a structured judgment instead of writing text, and Jev, released in early access by TypeSafe AI in September 2026, is the first one to make the category legible. As of September 2026, after 15 years leading product and platform teams through AI adoption in regulated environments, the part that interests me is not the speed. It is what happens to an organization when the cost of making a decision falls by two orders of magnitude, and what that reveals about which part of a decision was ever the hard part.
What is Jev, and what is a System One model?
Jev is a model from TypeSafe AI that returns structured decisions rather than generated text. TypeSafe calls the category System One models, after the fast, automatic mode of human thinking: the work is a judgment software can act on directly, not a paragraph a person has to read first.
The naming borrows from Kahneman, and the borrowing is apt. System Two deliberates — it reasons, it explains itself, it takes time. System One recognizes. You do not reason your way to "that noise was a door closing." You arrive at it whole, immediately, with a confidence you could not fully articulate.
Nearly every AI product of the last three years has been built on the deliberating machine. We have been asking a model that writes essays to tell us whether a support ticket is about billing.
How is Jev different from a traditional LLM?
A traditional LLM produces an answer sequentially, one token at a time, as freeform text. Jev generates its output in parallel in a single query, constrained to a schema you define in advance, and returns a calibrated probability alongside it. It is a different machine, not a faster version of the same one.
| Traditional LLM | Jev | |
|---|---|---|
| Sampling | Sequential, token by token | Parallel, all outputs in one query |
| Output | Freeform string | Type-safe value from a fixed schema |
| Training | RLHF / RLVR | RLCD — Reinforcement Learning for Calibrated Decisions |
| Confidence | Inferred, unreliable | Calibrated probability on every output |
| Response time | 3–329 seconds | 70–500ms |
| Cost | Input and output tokens | $0.042 per million input tokens, output free |
The row that matters is the first one. Everything else follows from it.
Because the output space is fixed before the question is asked, the model cannot hallucinate and cannot return a type error. Those are not behaviors that were trained out of it. They are outcomes the architecture does not permit — the same way a multiple-choice form cannot return an essay. That is a real guarantee, and it is worth being precise about what it guarantees: the answer will be well-formed and drawn from your options. Not that it will be right.
What is Jev actually good for?
Decisions where the set of possible answers is known before you ask: routing, classification, scoring, extraction, verification, and running the same judgment across a large dataset. It answers three shapes of question — pick from these options, rate this on this scale, or how likely is this statement to be true.
This is the unglamorous layer underneath most agent architectures, and it is where a lot of money currently goes to waste. An agent that reads a ticket, decides which queue it belongs in, and routes it is making one small judgment and paying frontier-model prices for a paragraph nobody reads. Independent testing put 4,148 input tokens through eight of these judgments for a fraction of a cent, at 92 to 214 milliseconds each.
The interesting applications are the ones that were never built because the economics did not work. Scoring every support conversation instead of a sample. Checking every agent's claim of success against the evidence rather than trusting the summary. Verification has always been the expensive half of automation, and it just got cheap.
What should you still use an LLM for?
Anything where the output space is not knowable in advance. If you cannot enumerate the possible answers when you write the code, a decision model has nothing to choose from, and a language model is the right tool. TypeSafe says this plainly: Jev is not for chat or freeform text.
The division is cleaner than most technology transitions allow. Drafting a reply to a customer is generation. Deciding whether that reply needs a human to read it first is a decision. One system is bad at the other's job, and the productive question is not which model wins but which half of your workflow you have been paying the wrong machine to do.
Most production systems will run both. The decision model routes, filters and verifies; the language model writes the thing a person actually reads.
Where does a decision model fail?
When the option set is wrong. Independent testing found that a forced choice with no escape hatch produced answers that were confident and incorrect, because the model will always pick from what it was given. A calibrated probability describes confidence within your options, never whether your options were any good.
This is the part I would put on a wall. The model is genuinely excellent at choosing. It has no opinion whatsoever about whether the choices are the right ones, whether "none of these" belongs on the list, or whether this decision should have been automated at all.
A calibrated probability is a seductive artifact. It looks like rigor. It reads like a number that has been earned. But 0.94 means the model is confident given a frame you built, and if you forgot to include the option that was actually correct, it will still hand you 0.94 — on the wrong answer, in a well-formed schema, in 200 milliseconds, for a fraction of a cent.
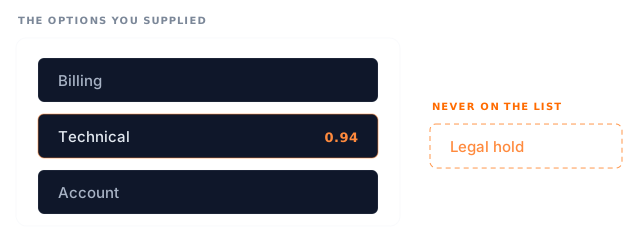
The 0.94 is real. It describes confidence inside the frame — and you drew the frame.
I have written before that a scoring rubric is only worth it if you let it win, and that the discipline lives in the weights you fix before you see the ranking. Same structure here. The quality of every decision this model makes was determined by whoever wrote the option list, and that person is not in the loop at runtime.
Two honest caveats on the evidence so far. The testing was eight synthetic cases, which the testers themselves say is not production-grade reliability. And nobody has published a head-to-head benchmark against a comparable LLM — the speed multiples circulating this week are TypeSafe's own figures, not an independent comparison.
What happens when decisions get cheaper?
You make far more of them. TypeSafe named the model after William Stanley Jevons, the economist who observed that more efficient steam engines increased coal consumption rather than reducing it. The constraint that kept trivial decisions un-automated was cost, and that constraint is going away.
TypeSafe makes this argument explicitly, and it is the most interesting thing about the launch. Each order of magnitude of efficiency unlocks use cases that were previously not worth it. That is presented as the opportunity, and it is. It is also the risk, stated in the same sentence.
For most of the last decade, cost was doing quiet governance work nobody credited it for. Plenty of decisions went unautomated not because someone judged them too sensitive, but because running a model over every row was too expensive to bother. That filter is about to disappear, and nothing has been designed to replace it.
So the question stops being can we automate this judgment and becomes should anyone be making this judgment at all, and who decided what the options were. That question has no API. It is product work, and it gets harder exactly as the technical constraint that used to answer it for free goes away.
The model doesn't choose the choices. Somebody still has to.